Protecting Tier-0 identity services is critical because failures amplify through retries. This approach ensures five-nines availability by using latency-based load shedding and decentralized quota management to stop cascading failures before they impact the entire distributed system.
By Ramya Subramani and Prateek Vats
In our Engineering Energizers Q&A series, we highlight the engineering minds driving innovation across Salesforce. Today, we spotlight Ramya Subramani, Vice President of Engineering. Ramya leads the Cloud Atlas team, which operates the globally distributed identity data store behind a large portion of Salesforce authentication. Every login and token validation that depends on Cloud Atlas requires fast, reliable identity data while the team maintains five nines of availability, roughly five minutes of downtime per year.
Explore how Ramya’s team redesigned distributed rate limiting and service protection with intelligent load shedding and coordinator-free global quota management to prevent cascading failures, isolate noisy neighbors, preserve five nines availability, and keep Salesforce authentication resilient under unpredictable traffic spikes.
What is your team’s mission, and why has protecting Salesforce’s identity platform become one of the hardest availability challenges you face?
The mission is to operate the globally distributed identity data store that powers a large portion of Salesforce authentication. When users or services sign in, the identity platform must determine who they are, which tenant they belong to, and what they are authorized to access. That identity data is maintained across multiple regions while delivering five nines of availability, roughly five minutes of downtime per year.
That mission becomes especially challenging because authentication sits at the front door of Salesforce. When identity slows down, the impact does not remain isolated inside Cloud Atlas. Dependent services begin waiting. Requests start queuing. Upstream systems retry. Those retries generate even more traffic against a system that is already under pressure, creating the conditions for cascading failures that can spread far beyond the original bottleneck. At this layer of the platform, a localized overload can rapidly become a much larger availability problem.
The challenge has grown harder as automation and agent-driven workloads introduce traffic patterns that are significantly more bursty and less predictable than traditional human logins. Protecting the identity layer is no longer just about serving requests quickly. It requires recognizing overload before retries begin amplifying it, isolating traffic spikes before they affect other tenants, and ensuring one customer’s surge never becomes everyone else’s outage.
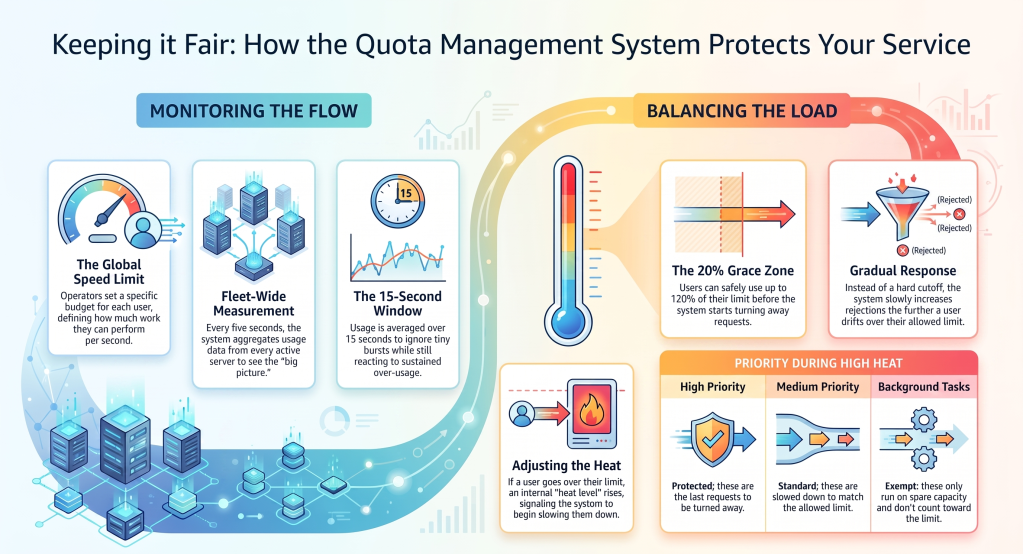
The previous protection model relied on per-instance rate limiting, which worked reasonably well when infrastructure remained relatively static. As Cloud Atlas adopted autoscaling and traffic became increasingly dynamic, that distributed rate-limiting model began working against the platform. Every server maintained its own limits, which became outdated whenever instances were added, removed, or customer traffic shifted. More importantly, each server understood only its own workload rather than total customer usage across the fleet. Busy servers could reject requests even while capacity remained available elsewhere.
The team also faced the noisy-neighbor problem. Because Cloud Atlas is multi-tenant, one customer’s unexpected traffic spike could consume shared resources and negatively affect unrelated tenants. Tuning thresholds alone could not solve that because the architecture itself was protecting individual servers rather than the service as a whole.
That led to redesigning service protection around global awareness, combining coordinator-free global quota management with intelligent load shedding so the platform could adapt as infrastructure and traffic evolved while preserving fairness and availability.
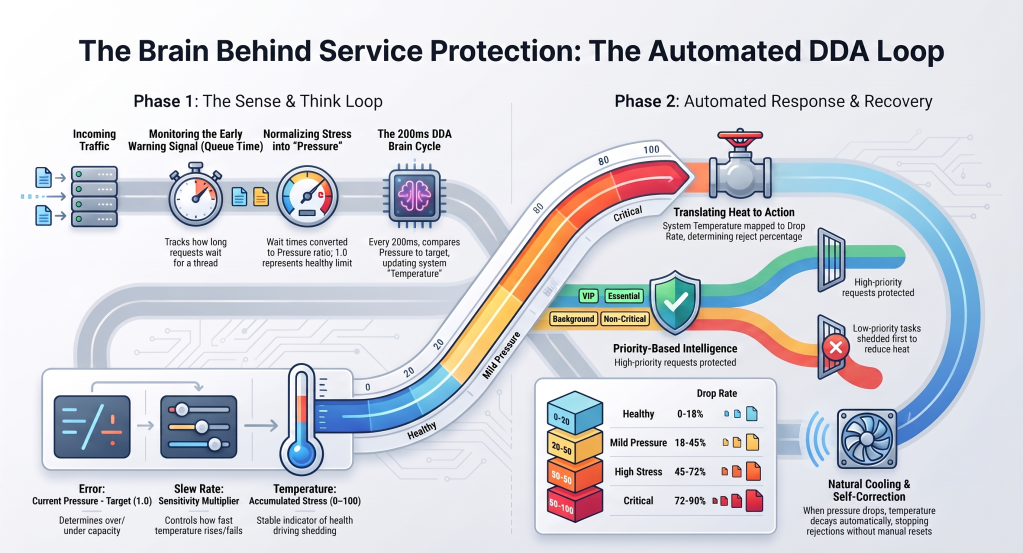
One of the biggest challenges with overload is that it does not fail politely; it amplifies. When requests begin slowing down, upstream services retry. Those retries generate additional traffic, placing even more pressure on a system that is already struggling. Latency increases, queues continue growing, retries multiply, and overload can quickly spiral into widespread failure.
Because Cloud Atlas is a shared dependency for identity services, those failures do not remain isolated. Authentication and token validation depend on the ability to respond quickly, which means localized overload can propagate through dependent systems and dramatically increase the blast radius.
Rather than waiting for error rates to spike, the team monitors queue time as an early indicator of system pressure. Latency rises before requests begin failing, giving intelligent load shedding an opportunity to react while the system is slowing down rather than after cascading failures have already begun. The objective is graceful degradation before temporary overload becomes an outage, not eliminating every slowdown.
One of the biggest design principles was ensuring that the system protecting availability never became another single point of failure. Centralized rate limiting sounds straightforward, but it introduces another critical dependency directly into the request path that can become the bottleneck it is supposed to prevent. Per-instance rate limiting created a different problem: autoscaling made static limits increasingly inaccurate, allowing busy servers to reject requests while capacity remained available elsewhere. Reducing operational complexity was also a priority because every additional threshold and tuning parameter creates another opportunity for incorrect behavior.
Rather than continuing to tune increasingly complex rate-limiting rules, service protection was redesigned around two complementary capabilities.
The first is intelligent load shedding. The system measures queue time to estimate system pressure and automatically adjusts throttling as pressure increases, shedding lower-priority work before higher-priority requests such as interactive logins.
The second is coordinator-free global quota management. Servers measure customer usage and share that information to independently reach throttling decisions without relying on a centralized coordinator. The approach adapts as servers scale up or down while preventing a noisy tenant from consuming shared capacity intended for everyone else.
Together, these capabilities allow the system to degrade gracefully while preserving availability and fairness as traffic patterns evolve.
Several principles from this work apply broadly to engineers building highly available distributed systems:
Maintaining five nines is not the result of a single algorithm. It is the result of designing a distributed system to absorb pressure, degrade gracefully, and recover predictably before localized overload has a chance to become a platform-wide outage.
The post How Intelligent Load Shedding Prevents Cascading Failures in Tier-0 Systems appeared first on Salesforce Engineering Blog.
Continue reading on the original blog to support the author
Read full articleModern DDoS attacks use AI to strike at machine speed, making human-led defense obsolete. Salesforce's DREAM platform demonstrates how combining AI-driven inference with durable execution and AI-assisted coding can protect hyperscale, multi-tenant clouds against sophisticated threats.
For global-scale perimeter services, traditional sequential rollbacks are too slow. This architecture demonstrates how to achieve 10-minute global recovery through warm-standby blue-green deployments and synchronized autoscaling, ensuring high availability for trillions of requests.
Securing AI agents at scale requires balancing rapid innovation with enterprise-grade protection. This architecture demonstrates how to manage 11M+ daily calls by decoupling security layers, ensuring multi-tenant reliability, and maintaining request integrity across distributed systems.
Managing complex enterprise systems requires more than identifying errors; it requires context. This approach allows engineers to prioritize remediation by linking static configurations to real-world runtime behavior, reducing decision paralysis and improving system scalability.
