Engineers must solve the context problem: balancing data relevance with cost and security. This architecture shows how to build a scalable, governed pipeline that decouples enterprise data from LLMs, ensuring agents act on trusted, real-time evidence without overloading prompts.
By Raveendrnathan Loganathan and Tobias Muehlbauer.
How do you compile the smallest sufficient body of current, relevant, and authorized evidence for every agent turn but without loading the entire enterprise data estate into every prompt? That is the context problem at the center of enterprise AI.
Putting everything into every prompt consumes tokens, increases latency and cost, buries relevant evidence, and exposes sensitive information. Avoiding that brute-force approach creates a distributed-systems challenge. The runtime must identify the requester, purpose, authority, entities, and freshness requirements before retrieving evidence across structured and unstructured data, knowledge graphs, streaming signals, and ingested or federated sources. It must then reconcile conflicting information and apply access, masking, residency, consent, and purpose controls, all within explicit token, latency, freshness, and cost budgets while preserving approved memory without turning every interaction into enterprise truth.
To address these requirements, Salesforce built Data 360 as a shared runtime foundation for Trusted Context across Salesforce, external data platforms such as Databricks and Snowflake, operational systems, documents, and knowledge bases. Its Q2 FY27 production usage demonstrates the scale of that foundation: 104.3 trillion connected records, including 81.5 trillion Zero Copy rows.
What this changes for enterprises:
Enterprise information begins as business records, documents, knowledge, live signals, and data distributed across multiple platforms. For each request, the runtime must reduce that entire estate to the subset that is both relevant and authorized.
To perform that reduction, Salesforce developed a progressive context pipeline in Data 360. The platform connects enterprise data through ingestion and Zero Copy, then harmonizes, unifies, infers, and models that information as knowledge. From there, the Agent Context Engine selects authorized evidence and delivers precisely scoped context to humans, applications, and agents.
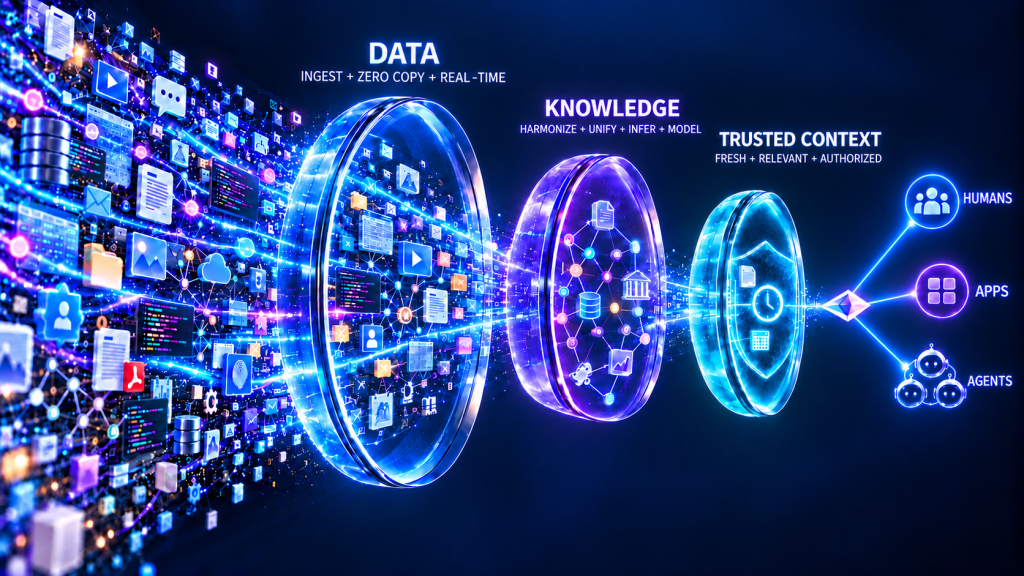
From enterprise data to Trusted Context.
Separating enterprise data from runtime context allows models, applications, and agents to evolve without requiring customers to rebuild business meaning, policy, or approved memory. It also allows data to remain authoritative in Salesforce, Databricks, Snowflake, and operational systems while participating through federation and Zero Copy.
Salesforce is building the Enterprise AI Harness to connect AI models to the customer’s business so AI can understand enterprise context, act across systems, and operate under enterprise control. The Harness brings together six trusted capabilities: Models, Context, Agency, Actions, Governance, and Security. A common AI Control Plane provides registry, identity, policy, lifecycle, observability, and cost control. As AI execution spreads across teams, applications, and third-party systems, this shared architecture provides visibility and control while allowing customers to compose the capabilities they need.
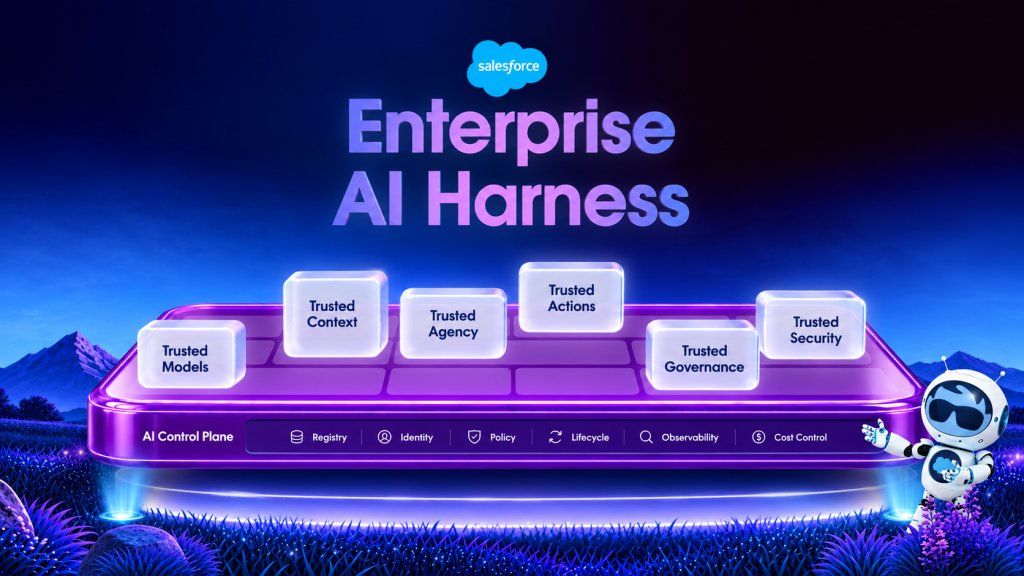
The six Enterprise AI Harness capabilities.
Trusted Models manage model lifecycle and route work to the appropriate model, while Trusted Agency supplies reasoning and orchestration. Trusted Actions connect agents to applications, APIs, tools, and workflows. Trusted Governance and Trusted Security apply lineage, quality, identity, permissions, privacy, and policy. Trusted Context anchors these capabilities by supplying the governed evidence and continuity on which reasoning and execution depend. Data 360 connects enterprise systems, resolves business entities and relationships, retrieves structured and unstructured knowledge, applies policy, carries approved memory, and records the evidence behind answers and actions.
This separation allows models and interaction channels to change while the underlying business context endures. For that context to become useful at runtime, however, it must be compiled for the requirements of each agent turn.
To support context assembly and governed continuity, the Agent Context Engine operates bidirectionally. On the outbound path, it compiles authorized context for each agent turn. On the inbound path, conversations, tool calls, decisions, actions, and outcomes return as typed interaction traces for auditing, evaluation, and correction. These traces may remain in short-term memory; only approved facts are promoted into durable memory, and only validated outcomes are distilled into learnings.
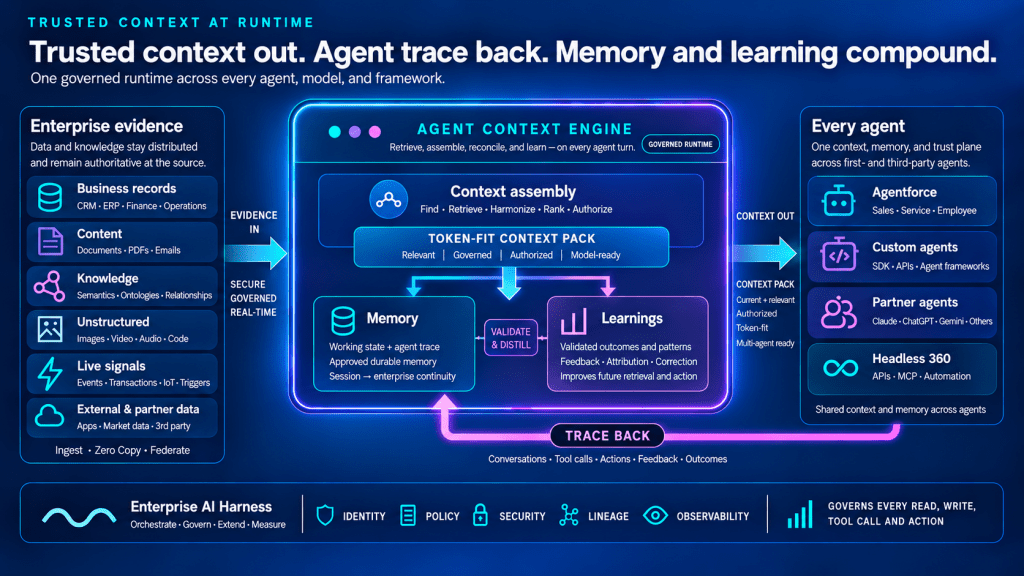
How Trusted Context works for agents at runtime.
On the outbound path, the Agent Context Engine retrieves, reconciles, authorizes, and assembles enterprise evidence into a token-fit Context Pack. The Context Pack can support Agentforce, custom agents, partner agents, and Headless 360. On the inbound path, typed interaction traces return for audit and evaluation. Approved information may be promoted into durable memory, while validated outcomes can become learnings that improve subsequent Context Packs.
The team divides context assembly for AI agents into six runtime stages:
The resulting Context Pack contains the minimum authorized evidence, memory, and learnings a person, application, or agent requires to complete a task. Rather than exposing the complete enterprise estate to the model, the Agent Context Engine applies policy and provenance before compiling that context within explicit runtime budgets. Because context assembly operates as a shared runtime service, the team can measure it consistently across agents. Those measurements include useful evidence per token, retrieval precision, time to first context, memory continuity, and cost per authorized outcome.
A model context window is temporary, but enterprises need governed continuity across models, agents, applications, and channels. To provide that continuity in Data 360 without treating every interaction as durable enterprise knowledge, the team separates runtime state into four forms:
A transcript records what happened; it does not automatically become enterprise memory. Memory preserves what is approved to endure, while learning determines what should change. By maintaining these distinctions, Data 360 can use validated outcomes to improve future context without permanently promoting every interaction. Approved memory can persist across experiences even as models, agents, applications, and channels evolve.
Trusted Context is a strategic layer built on an existing production foundation. Data 360 unifies data, knowledge, context, memory, and query across a distributed enterprise estate, while the Enterprise AI Harness connects that context to governed action. The Agent Context Engine operates above unified query and retrieval, multi-model data services, processing and intelligence, storage and compute, trust, and open connectivity. Together, these layers support relational queries, profile lookups, graph traversal, keyword and vector search, RAG, streaming data, identity resolution, document understanding, knowledge modeling, and policy enforcement.
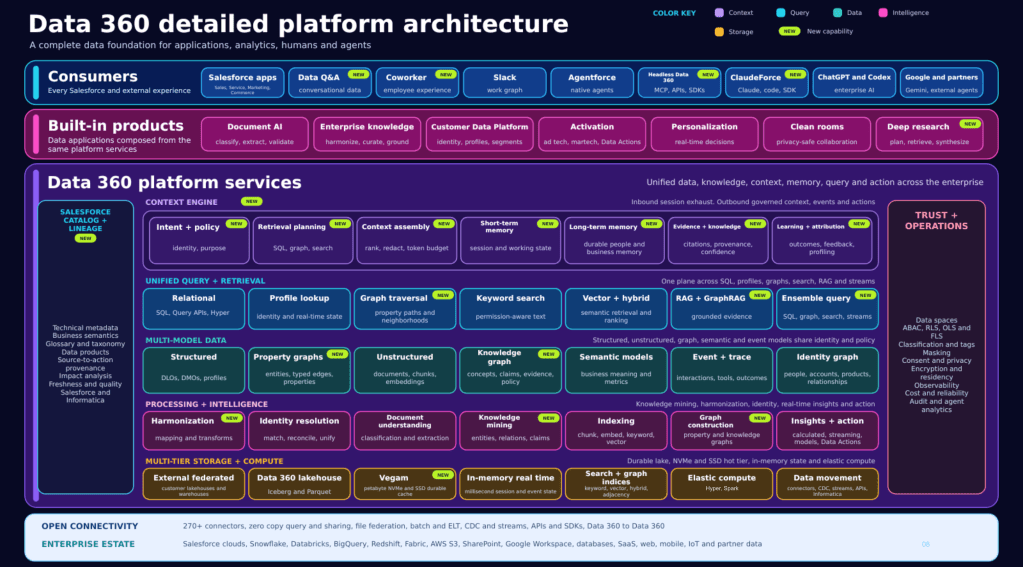
Data 360 detailed platform architecture.
Salesforce and external experiences connect to built-in data applications and the underlying Data 360 platform services. Trust and operational controls span the platform, while open connectivity extends it to Snowflake, Databricks, BigQuery, Microsoft Fabric, AWS, and other enterprise systems. Rather than requiring customers to centralize every dataset in one stack, Data 360 operates across a distributed enterprise data estate. Data can remain authoritative in Salesforce and external platforms while participating through ingestion or Zero Copy federation.
The breadth and velocity of this foundation are visible in Data 360’s Q2 FY27 production usage. The platform processed 12.7 quadrillion records and 9.7 quadrillion query records. It connected 104.3 trillion records, including 81.5 trillion Zero Copy rows, approximately 78% of all connected records. The same period included 22 terabytes of unstructured data, 25.3 billion unified profiles, 2 trillion activated records, and 41 billion action events. Customer names are excluded.
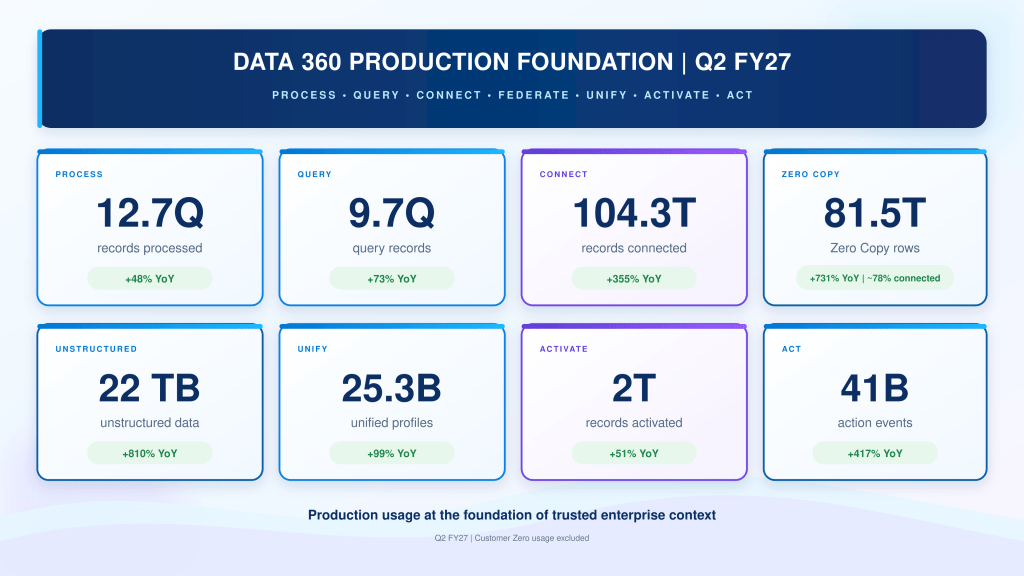
Data 360 Q2 FY27 production usage.
These workloads already span a distributed enterprise estate and flow through unstructured processing, profile unification, activation, and action. The next requirement is carrying that foundation across multiple agent types and interfaces without fragmenting context, memory, or governance.
The architecture establishes a shared context, memory, and trust plane across Salesforce applications, Agentforce, custom agents, partner agents, and external experiences. These consumers can use consistent context, authority, action, and observability contracts.
Pro-code agents can use SDKs and API adapters to request context, invoke governed tools, and stream typed interaction traces back to the Enterprise AI Harness with identity, correlation, provenance, and outcome signals. SaaS assistants, including Claude, ChatGPT, Copilot, and Gemini, can use a parallel path through MCP and APIs. Across both paths, Data 360 resolves identity, semantics, policy, freshness, memory, and evidence before the model receives them. This architecture allows customers to change models, agents, and interfaces without rebuilding business meaning, permissions, memory, and tool governance.
This is the promise of Headless Salesforce: the Harness is designed to travel with the work across Slack, Agentforce Coworker, third-party agents, custom applications, and future interfaces while preserving the same governed context, actions, security, and trust boundaries. Extending the architecture across those consumers establishes its reach. The remaining question is whether the underlying systems can assemble context interactively at production scale.
The team evaluates the Data 360 production foundation across four workload types: production retrieval latency, high-concurrency queries, analytical SQL, and graph queries. Because no single benchmark represents all four requirements, the results provide complementary evidence rather than components of a composite performance score. The workload types we are evaluating are powered by Hyper, our high-performance query engine at the heart of Salesforce Data 360. Hyper combines low-latency multi-modal query processing with a serverless Data 360 operating model built for high concurrency and varying workload complexity.
Production Agentic RAG, semantic and keyword search across structured and unstructured data, recorded p50 latency of 126 milliseconds and p90 latency of 352 milliseconds. In a separate high-concurrency test, Data 360 recorded median query latency of approximately 40 milliseconds at approximately 750 queries per second. Because these tests use different workloads, their results should be treated as complementary evidence rather than directly compared.
The ClickBench panel provides a third performance lens. Its analytical workload and methodology differ from the production Agentic RAG and high-concurrency tests, so the three panels are not directly comparable.
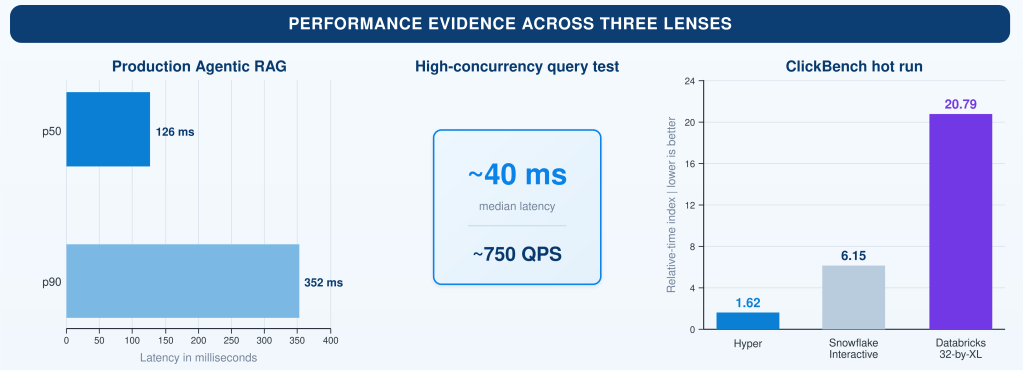
Performance evidence across three workload types.
The public ClickBench dashboard provides an independently inspectable analytical reference point, along with published methodology and reproduction scripts. It uses 43 queries over an anonymized dataset derived from production web-analytics traffic. A hot run is the second or third execution after caches have been populated. In the selected September 2026 snapshot, the relative-time indices were 1.62 for Hyper, 6.15 for Snowflake Interactive (32×2XL), and 20.79 for Databricks (32×XL). Lower is better. These are normalized runtime indices, not claims that one system is a corresponding number of times faster. ClickBench also notes that its workload represents a subset of database use cases and that its standard query sweep is not a concurrent-capacity test. Here, its results provide analytical-query evidence rather than a measure of end-to-end agent performance.
Representative TPC-derived geo-mean query times provide a separate analytical view. These workloads are not audited TPC results, and their configurations and test dates vary. For both TPC-H and TPC-DS benchmarks, all read queries defined by the respective benchmark were run. Each ratio divides the named platform’s runtime by the Hyper runtime: a value above 1.0 indicates a higher runtime than Hyper, while a value below 1.0 indicates a lower runtime.
| Workload | Hyper | Snowflake Interactive (2XL) | Snowflake Interactive (2XL) / Hyper | Databricks Pro XL | Databricks Pro XL / Hyper |
| TPC-H-derived SF100 | 0.175 s | 0.454 s | 2.6x | 2.228 s | 12.7x |
| TPC-H-derived SF1000 | 1.630 s | 1.474 s | 0.90x | 6.121 s | 3.7x |
| TPC-DS-derived SF100 | 0.091 s | 0.525 s | 5.8x | 1.687 s | 18.5x |
| TPC-DS-derived SF1000 | 0.496 s | 0.994 s | 2.0x | 2.576 s | 5.2x |
Geo-mean query time. Lower is better.
These TPC-derived results provide another view of the analytical processing that supports context workloads. Like the preceding measurements, they should not be collapsed into a single platform ranking.
Graph relationships are also part of enterprise context. The LDBC Social Network Benchmark Business Intelligence workload focuses on aggregation- and join-heavy queries that touch a large portion of a graph. In LDBC BI-derived tests, Hyper running property graph queries recorded a geo-mean query time of 0.059 seconds, compared with 0.184 seconds for the evaluated Neo4j configuration at SF1. At SF10, Hyper recorded a geo-mean query time of 0.167 seconds, compared with 1.514 seconds for Neo4j. These measurements examine the graph traversal required to incorporate business entities and relationships into enterprise context. The small-scale, non-audited comparisons apply only to the evaluated configurations and do not establish general graph-database leadership.

Hyper running property graph queries (PGQ) and Neo4j graph-query performance.
Together, these production, concurrency, analytical SQL, and graph-query measurements establish a performance baseline for Data 360’s context workloads. Each result remains confined to its published workload, configuration, and test method. They demonstrate that Salesforce can execute demanding context workloads without making a universal database-ranking claim.
The Data 360 performance evidence above establishes whether the underlying systems have the foundation required for context assembly. However, traditional data benchmarks do not measure the complete workload an AI agent performs across structured records, unstructured content, search, relationships, memory, fresh events, and source-specific permissions.
To address that gap, the team proposes an Agentic Context Benchmark that measures answer correctness, access enforcement, masking, provenance, local and federated retrieval, mixed-concurrency latency, context size, useful evidence per token, freshness, cost, memory continuity, and improvement from validated outcomes. Under this benchmark, a result would count only when the resulting action is both authorized and completed. Salesforce intends to help define this workload openly with customers, partners, vendors, and researchers as a practical standard rather than a test optimized for one architecture.
Data platforms will continue to store and compute data, while AI models, agents, applications, and interfaces continue to change. The enduring control point is the layer that understands the business, assembles Trusted Context, applies policy, preserves approved memory, and connects reasoning to action.
Salesforce is building the Enterprise AI Harness to provide that system. Data 360 powers its Trusted Context capability through production scale, high-performance query, federation, business meaning, memory, learning, and governance. Compiling context for today’s agent turn is only part of the requirement. The surrounding system must enforce applicable controls, preserve approved state, and carry validated outcomes across whatever models, agents, applications, and channels come next. That is the enduring layer Trusted Context is built to provide.
Many of the technologies forming the foundation of Salesforce’s Enterprise AI Harness are available today. New capabilities and the unified experience are planned to begin rolling out in early FY28. Availability may vary by product, region, and customer agreement.
The post How Data 360 Builds Trusted Context: The Enduring Layer for Enterprise AI appeared first on Salesforce Engineering Blog.
Continue reading on the original blog to support the author
Read full articleEngineers must balance LLM creativity with deterministic reliability. This approach shows how to prevent hallucinations and ID corruption in complex workflows by using orchestration graphs and state management to ensure AI outputs remain functional and grounded.
Scaling distributed systems to 120 trillion rows requires moving beyond query federation. Adopting a file-based approach with Apache Iceberg eliminates bottlenecks between compute and storage, enabling high-performance AI at petabyte scale without data duplication.
Scaling real-time conversational data is critical for AI agents requiring immediate context. This architecture shows how to balance high-throughput ingestion with low-latency retrieval, ensuring consistency in distributed systems even under extreme traffic spikes.
This article demonstrates how to build scalable, autonomous AI agent systems that overcome infrastructure constraints like rate limits. It provides a blueprint for moving from LLM prototypes to production-grade systems that drive significant business value through automated workflows.
