This report details the practical challenges of large-scale cloud migration and database scaling. It provides valuable lessons on implementing failure containment, overload controls, and the necessity of monitoring primary database health during background maintenance tasks.
Our last update covered content through August. We did not publish another in September while other public content addressed the August 17 outage. This edition covers progress over the past two months.
The short version of August and September: we reduced shared-database pressure, added overload controls, created headroom for GitHub Actions, expanded failure containment for pull requests, and moved more production workloads to Azure. Significant incidents, a capacity pause, and a missed migration target show that the work is not complete.
By October 7, 120 of 160 production services were deployed in Central US, and 13 of 51 primary MySQL databases had moved. Azure also handled 65.4% of read traffic for GitHub’s core application, 48.3% of Git read traffic, and 80.2% of stream-processing traffic. These percentages measure different workloads and should not be added.
We paused Central US deployments and traffic increases on September 11 because capacity was uneven across availability zones. Permanent ramps resumed September 18 after temporary relief, but durable capacity work continues, with a goal of unlocking all available capacity by the end of October. We missed our aggressive September 30 goal to deploy every production service there. During a planned database failover, an automated emergency process disconnected Central US database copies and disrupted customers in that region. We disabled that process during planned handoffs while improving recovery.
Outside the regional migration, 24 authentication-core tables moved off GitHub’s oldest shared database, removing approximately one million queries per second from its replicas. The database cluster supporting issues and pull requests removed approximately 980 million unnecessary edit-history rows, creating an estimated 1.8 terabytes of recoverable storage. Weekly deadlocks fell approximately 77% from their June peak, and continuous cleanup now prevents the same unbounded growth from returning.
Half of sampled pull request traffic can now continue with limited functionality when a shared dependency fails. Production results showed several read operations remained available during a shared-database incident. Database traffic routing can also add capacity automatically during spikes; one group expanded from 14 to 19 instances during a September 23 increase in pull request activity. A production overload control now lets responders protect higher-priority API and web workflows by rejecting lower-priority requests before broader saturation. Operator documentation and training are complete.
GitHub Actions also gained operating headroom. Production changes reduced measured Redis operations by approximately 28% and relative CPU by approximately 30%. A separate infrastructure cache reduced Redis bandwidth by 84%, average response time by 66%, median response time for the primary inventory request by 96%, and queued requests by 95%.
The August 6 actions outage, August 17 github.com outage, September failover disruption, and controlled capacity pause are reminders that measured improvements matter only when they reduce customer risk under real conditions. The principle remains the same: availability, then capacity, then features.
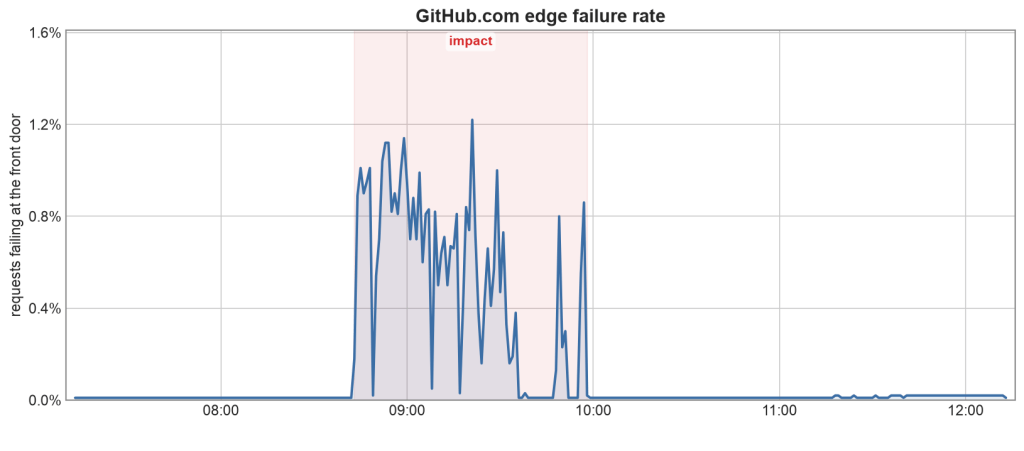
A background data-cleanup job increased load on a shared database. The job had a safeguard designed to slow its writes when database replicas fell behind, but the safeguard did not account for incoming load on the primary database server. As a result, the job continued running until the primary reached its connections limit. When the primary ran out of available connections, requests that depended on it could not complete reliably.
Two other factors increased the impact and delayed recovery. First, there was no quick timeout on these database calls, so request handlers waited on the stalled database instead of failing fast. Second, a retry loop around token creation kept resending writes that were already failing, which held the database saturated rather than letting it recover.
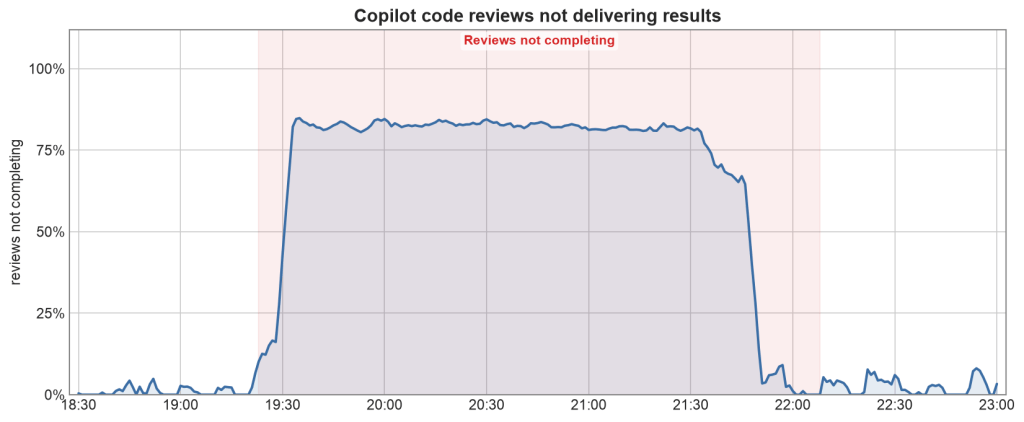
Copilot code review uses a separate service to run reviews and 2 versions of the results are returned: a limited copy that excludes the review comments and a full copy that includes the completed review. Copilot code review posts reviews only from the full copy. A change to that service began sending the full copy only for some customers. For other customers, only the limited copy was sent.
As a result, Copilot code review could not build a review, but reported that the job had completed successfully. The missing review results were not detected due to lack of monitoring. The incident was detected as some of the reviews remained incomplete for more than 30 minutes, triggering an alert to first responders.
We mitigated the incident by reverting the change.
Follow our status page for real-time updates on status changes and post-incident recaps. To learn more about what we’re working on, check out the engineering section on the GitHub Blog.
The post GitHub availability report: September 2026 appeared first on The GitHub Blog.
Continue reading on the original blog to support the author
Read full articleGitHub is evolving its Git storage to handle agentic scale by moving to Azure and decoupling storage from compute. By implementing per-reference serialization, they overcome cross-region latency bottlenecks and enable independent scaling of read and write traffic.
This report highlights the complexities of scaling a massive platform while migrating to cloud infrastructure. It provides insights into managing database hotspots, handling cascading failures in service meshes, and the critical trade-offs between availability and feature velocity.
This report illustrates the complex reality of migrating a massive monolith to the cloud. It highlights how architectural isolation, dedicated services, and automated safeguards are essential for maintaining availability while scaling and moving away from legacy shared infrastructure.
This report provides a transparent look at large-scale infrastructure migration and service extraction. It highlights the trade-offs between speed and stability, the importance of edge rate-limiting, and how to handle database contention in a massive monolith-to-microservices transition.
