Engineers must bridge the context gap for AI agents to be effective. This architecture shows how to deliver high-performance, secure, and unified customer data at scale, achieving sub-200ms latency while maintaining strict data isolation in complex enterprise environments.
In our Engineering Energizers Q&A series, we explore the engineering minds behind some of Salesforce’s most complex technical challenges. Today, we spotlight Alex Smith, Senior Director of AI Engineering, whose team uses Data 360 data graphs to give Agentforce something every personalized interaction depends on: trusted customer context. Their goal is to turn decades of fragmented information about customer identities, products, SKUs, services, and entitlements into a cohesive data foundation that agents can use to understand who they are helping and what matters to them.
But getting there meant tackling an extraordinary set of engineering challenges. How do you correctly connect a customer to products and entitlements buried behind layers of contracts, orders, and product hierarchies, without ever mixing one customer’s data with another’s? How do you model many-to-many relationships for agents that can ask questions you never anticipated? And how do you make all of that fast enough to disappear inside an AI interaction? Explore how the team tackled these challenges while driving personalized agent context to P50 performance below 200 milliseconds.
The mission is to close the context gap for agents. Agents do not inherently know who they are talking to, what products that person has or uses, what account they are associated with, or their history with Salesforce. Without that context, the system can provide generic knowledge, but it cannot personalize the experience around the customer.
That context can come from dozens of sources, with account information, entitlements, cases, and customer success data potentially using different identifiers. Data 360 data graphs perform the joins, aggregation, relationship management, and business logic upfront, turning those disparate data points into a cohesive data product.
The first Help Agent graph centered on tenant context. Instead of performing multiple queries, joins, and mappings, an agent can provide a tenant ID and retrieve relevant context at runtime. The goal is bigger: build the graph once and make the same trusted customer context available to whichever agents need it, unifying that context into one callable object.
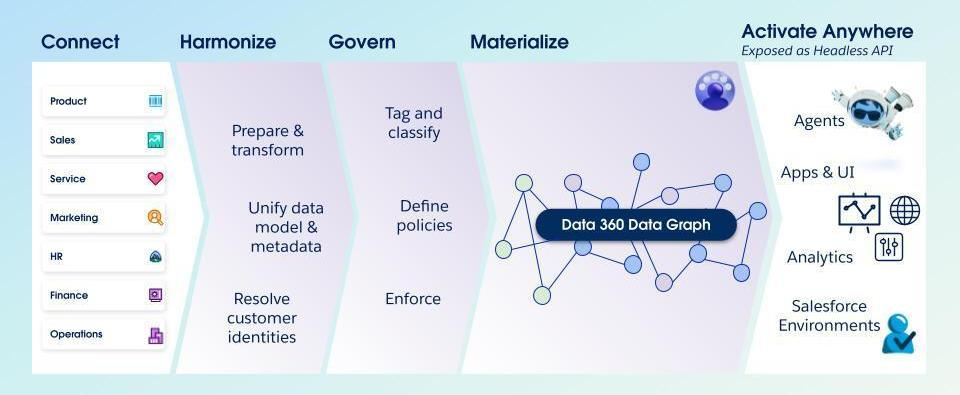
Data 360 harmonizes and contextualizes data for agents to consume.
“Who is this customer?” sounds simple. In enterprise data, it is not. Information can be scattered across systems, customers can have multiple product deployments, and products can span multiple customers. The relationships between the individual, account, tenant, organization, products, utilization, services, and entitlements must be preserved.
The entire identity universe cannot be exposed to an agent. The unified identity matrix supports marketing, sales, and other business motions, but a customer-success-specific view is needed that does not mix prospect data or one customer’s information with another’s. Precision around identity and data isolation is critical.
Data 360’s partitioned architecture addresses that. The broader identity graph resides in its own data space, while a filtered view is exposed to the customer success data space and locked down for specific agent-context and outreach use cases.
Agents may need multiple pieces of customer context, and they need them quickly. The process starts by understanding access patterns: how will agents actually use the data? Then the design is built around those questions, dividing the information into smaller graphs or multi-graphs. There is a balance. Make a graph too large and performance suffers. Make graphs too small and they must be joined at retrieval time, recreating the aggregation problem. Understanding access patterns also allows the team to build indices and retrieve relevant information rather than performing full table scans.
Earlier, the solution was benchmarked at about 400 milliseconds. More recently, live monitoring has shown P50 performance below 200 milliseconds.Data 360 also means the team does not have to build dedicated compute, autoscaling, REST APIs, and identity-serving infrastructure to achieve that performance.
This changes how the team thinks about data modeling. With humans, traditionally the use case was known and the model was optimized around expected questions a person might ask. With agents, the next question is not necessarily known, while the information returned still needs to be precise. Even answering “What products has this customer purchased?” can require traversing from a tenant to contracts, orders, order items, products, and multiple product hierarchies, then applying business logic around provisioning and activation. SKUs, mappings, product names, and purchases also change, so those relationships have to remain extensible.
Search therefore becomes part of the architecture. Agents receive natural-language questions, so the system needs to model many-to-many relationships, support semantic or keyword search, and let agents traverse the graph from different starting points. The team also learned that more is not more. Giving an agent every interaction, file, attachment, and data point does not necessarily make it smarter. Context is curated and summarized at the right grain so the agent gets what benefits its logic without being flooded with unnecessary information.
Historically, the individual pieces could require separate infrastructure: one tool to curate the graph, another to unify it, another to resolve identity, and additional capabilities to cache and serve the information. Different engineering teams could own different parts of that architecture. The team experienced that complexity firsthand. In a previous environment, building customer identity at scale involved roughly seven data scientists working on matching algorithms, four or five data engineers handling data input, and about 10 data architects and engineers operating the technical stack. Rebuilding a trusted identity and serving foundation from scratch could represent as much as a year of work.
Data 360 brings those capabilities together on a common infrastructure, allowing the team to focus engineering effort on the relationships, business logic, access patterns, and customer context that agents actually need.
Within six months, the team delivered five major releases. To move that quickly, reusable engineering practices were built so every new data product did not require the same plumbing. That included automating deployment and creating reusable data validations, such as verifying that primary-key counts match between source and destination. The team balanced delivering business value quickly with building assets that could make each subsequent delivery faster.
The team also had to make a relatively new technology easy for other teams to adopt. Integration paths were demonstrated through Postman calls, Apex queries, native Agentforce integrations, and low-code and no-code environments, proving that the architecture could scale and fit into different workflows.
The proof of concept showed that data graphs could solve the problem. Five graphs in six months showed that the team could build a reusable foundation where adding new customer context becomes a roadmap item rather than another infrastructure rebuild.
The post How AI Agents Get Trusted Customer Context with Data 360 Data Graphs appeared first on Salesforce Engineering Blog.
Continue reading on the original blog to support the author
Read full articleAs AI agents move to complex multi-system workflows, siloed security fails. This platform-centric approach ensures consistent identity, data, and API governance, preventing unauthorized access and ensuring auditability across distributed enterprise environments.
As AI agents become more autonomous, traditional governance fails. This integration provides engineers with deterministic lineage and tracing, allowing them to audit AI decisions, ensure data quality, and mitigate risks like hallucinations in complex, dynamic execution environments.
Scaling security operations manually is impossible in complex cloud environments. SATA demonstrates how AI agents can automate high-volume triage with 95% accuracy, allowing engineers to focus on critical threats while maintaining trust through confidence scoring and orchestration.
Enterprise AI requires real-time context and verifiability. This architecture solves hallucination problems by grounding LLMs in live web data with a citation engine, making AI outputs reliable for critical business decisions and ensuring transparency through traceable source metadata.
